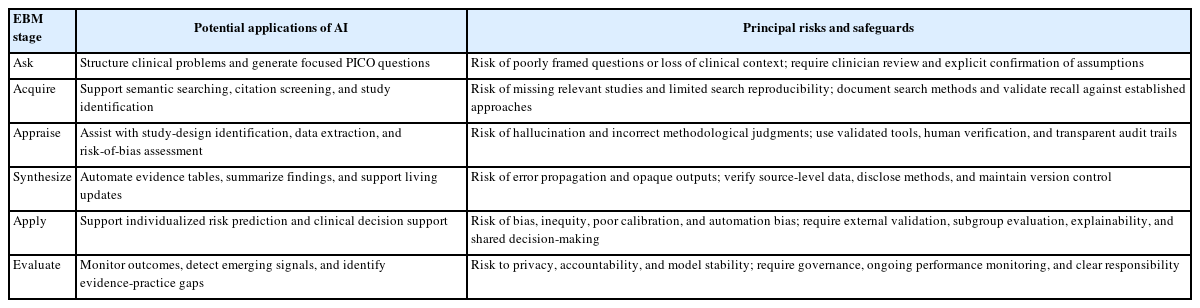
Evidence-based medicine (EBM) has transformed clinical decision-making by integrating the best available research evidence with clinical expertise and patients’ values and preferences. Over the past three decades, EBM has evolved from the critical appraisal of individual studies into a broader framework encompassing evidence synthesis, clinical practice guidelines, assessment of evidence certainty, research transparency, and shared decision-making. Despite these advances, contemporary EBM faces important challenges, including the rapidly increasing volume of research, delays in evidence synthesis and implementation, limited applicability of randomized controlled trials to heterogeneous real-world populations, and difficulties in individualizing population-level evidence. Emerging approaches—including real-world evidence, living evidence, learning health systems, precision medicine, and artificial intelligence (AI)—offer opportunities to address these limitations. Together, these approaches may enable a transition from static to continuously updated evidence, from population-average to more personalized evidence, and from a linear evidence pipeline to a learning evidence ecosystem in which clinical practice both uses and generates evidence. AI may further accelerate evidence retrieval, synthesis, updating, and individualized decision support, while introducing challenges related to reliability, bias, transparency, reproducibility, and accountability. Next-generation EBM should therefore be conceptualized not as a replacement for traditional EBM but as its evolution into a digitally connected, continuously learning evidence ecosystem. In the AI era, the foundational principles of EBM—source verification, critical appraisal, uncertainty assessment, integration of patient preferences, and accountable human judgment—will become increasingly important.
Background Large language model (LLM)–based tools are increasingly used to automate risk-of-bias assessment of randomized controlled trials with the revised Cochrane tool (RoB 2.0). However, their reproducibility, their accuracy, and their fidelity to the deterministic algorithm mapping signalling-question responses to domain judgments remain unclear.
Methods In a conference workshop, participants used an identical prompt and tool versions to assess one RCT with three configurations and entered each tool’s output verbatim (13, 15, and 10 runs). One experienced reviewer’s assessment served as the reference. For each run we computed run-to-run reproducibility, agreement with the expert, and conformance between the tool’s stated domain judgment and the judgment implied by applying the RoB 2.0 algorithm to that run’s own signalling answers.
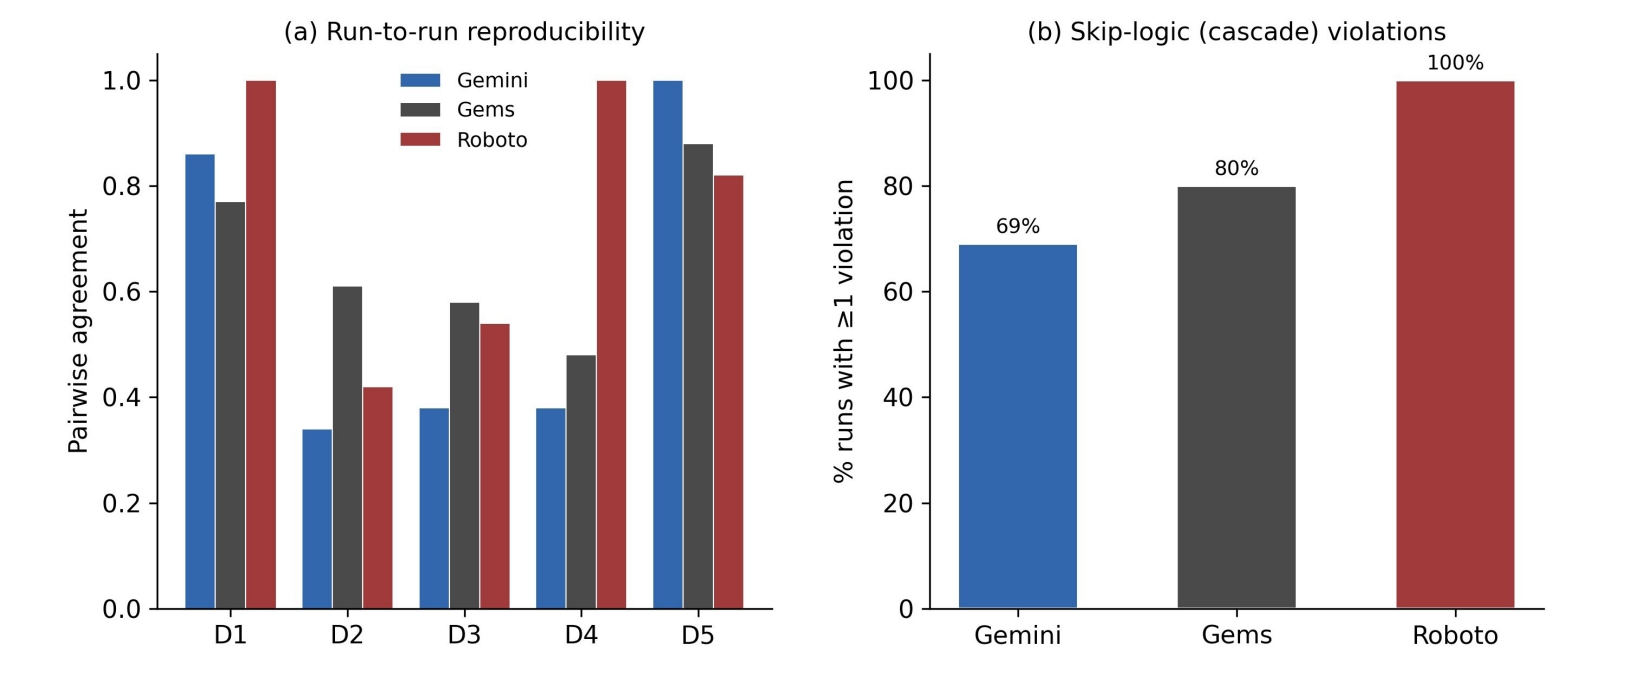
Results All configurations showed substantial run-to-run variability under identical conditions, greatest in the conditionally complex domain 2 (Gemini pairwise agreement 0.34). Expert agreement varied widely across configurations (mean 5–60%), and one configuration systematically under-rated risk. Even in domains with a fully specified algorithm, stated judgments frequently diverged from the value implied by the tool’s own signalling answers (domain 2, mean 42%). Skip-logic violations occurred in 69%, 80%, and 100% of runs. Recomputing domain judgments from the signalling answers improved expert agreement for the general-purpose configurations.
Conclusion LLM-based RoB 2.0 assessments exhibited variability and errors. Whatever tool is adopted, its characteristics and variability must be recognized. Having the tool perform only atomic (single) judgments while delegating aggregation to the algorithm, together with human review, may improve accuracy.
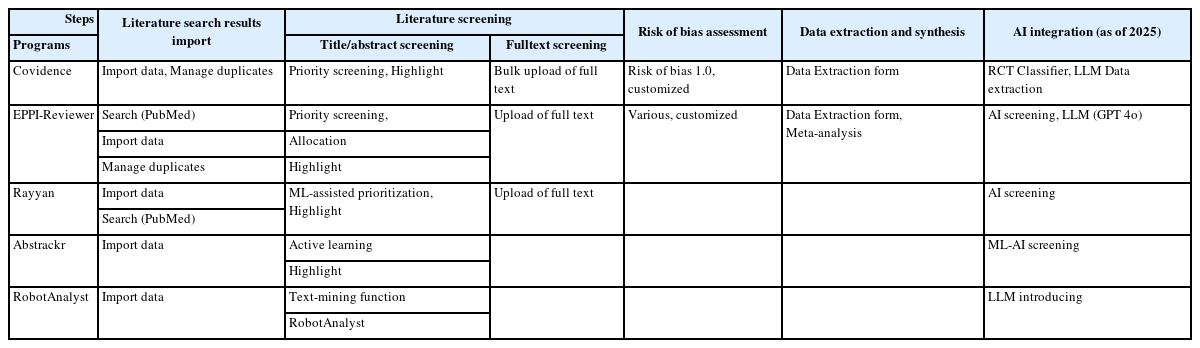
This review explores the current landscape of artificial intelligence (AI)-assisted semi-automation tools used in systematic reviews and guideline development. With the exponential growth of medical literature, these tools have emerged to improve efficiency and reduce the workload involved in evidence synthesis. Platforms such as Covidence, EPPI-Reviewer, DistillerSR, and Laser AI exemplify how machine learning and, more recently, large language models (LLMs) are being integrated into key stages of the systematic review process—ranging from literature screening to data extraction. Evidence suggests that these tools can save considerable time, with some achieving average reductions of over 180 hours per review. However, challenges remain in transparency, reproducibility, and validation of AI performance. In response, international initiatives such as the Responsible AI in Evidence Synthesis (RAISE) project and the Guideline International Network (GIN) have proposed frameworks to ensure the ethical, trustworthy, and effective use of AI in health research. These include principles like transparency, accountability, preplanning, and continuous evaluation. This review highlights both the opportunities and limitations of adopting AI in evidence synthesis and underscores the importance of human oversight and rigorous validation to ensure that such tools enhance, rather than compromise, the integrity of systematic reviews and guideline development.

 First
 Prev